
Choose a public site
Start with an HTTP or HTTPS URL. The analyzer validates the target, then looks for useful same-site pages through public navigation, links, and site-map signals.
How it works
Site Stripper maps a public URL, observes page structure and visual details, and organizes the evidence into a comprehensive ZIP. Give that reference to Claude, Codex, OpenCode, Cursor, and any other AI agent to guide a fresh website in the same visual style.
Start with an HTTP or HTTPS URL. The analyzer validates the target, then looks for useful same-site pages through public navigation, links, and site-map signals.
Pages are examined one at a time for headings, visible content, layout, design tokens, controls, media references, responsive behavior, and available captures.
Bounded observations are rendered into page notes, cross-page guides, and machine-readable files. Coverage notes keep partial results and known limits visible.
The browser validates the generated file set and assembles the ZIP. Screenshot binaries are included only when the corresponding captures are available.
The ZIP gives an AI coding agent a clear starting point for the reference site's visual DNA. Page notes explain what appears and in what order. Design tokens, responsive observations, and captures add the detail needed to carry the same style and art direction into a brand-new site or web app.
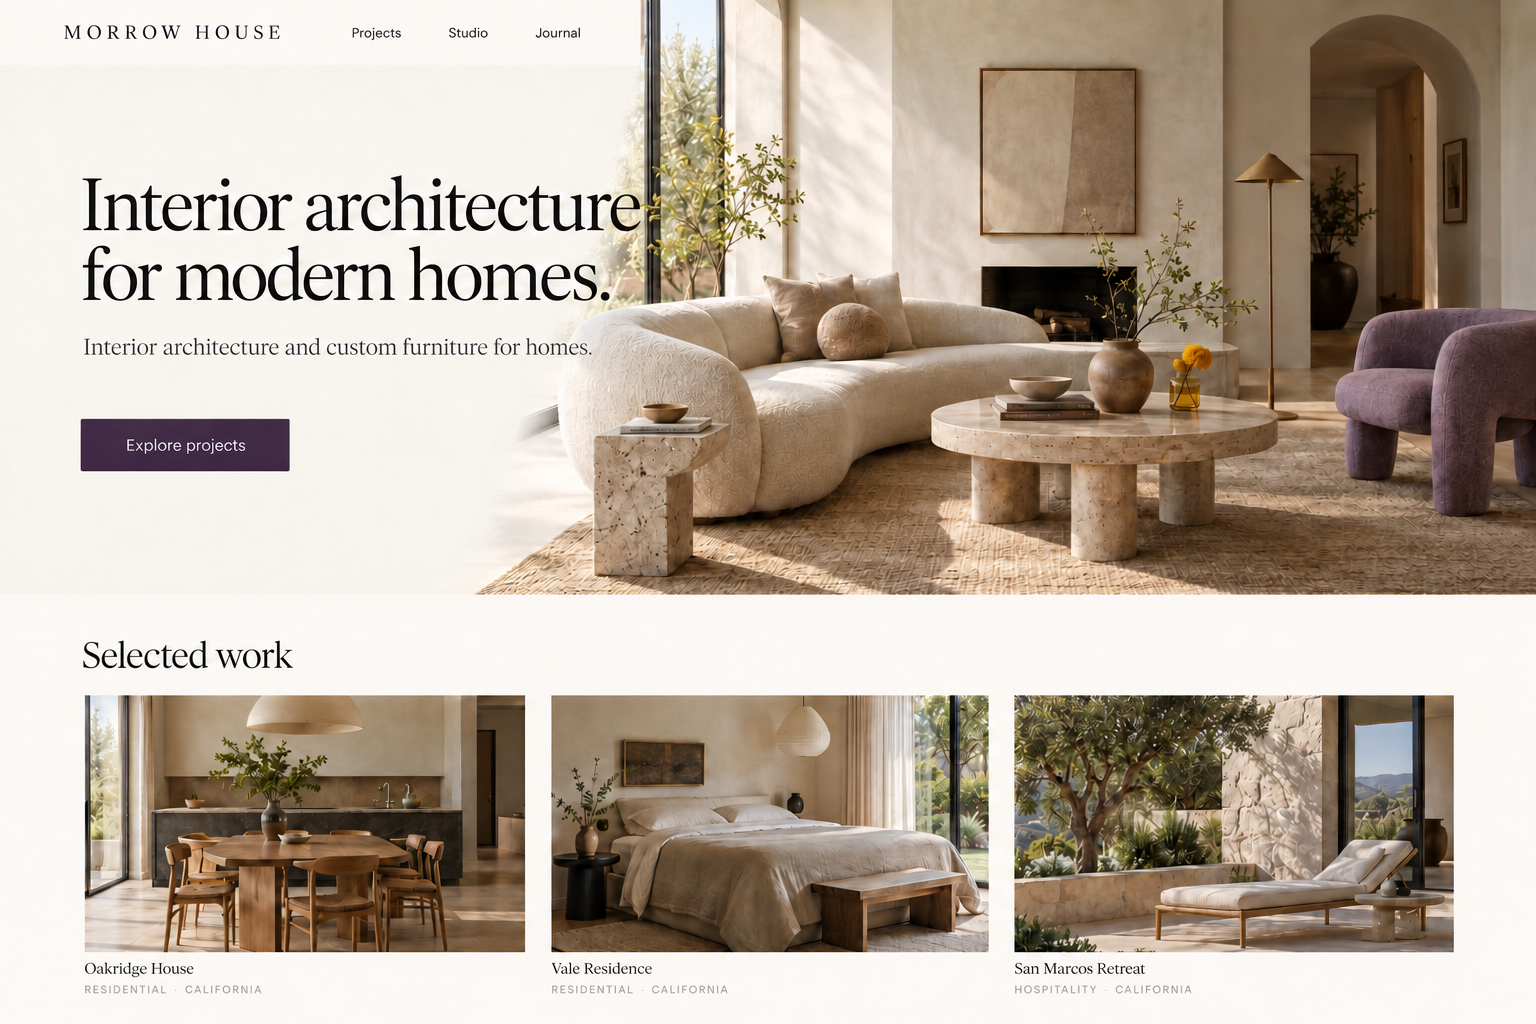
Observed page details
Headings, visible text, navigation, media references, and layout samples are recorded alongside the page where they were observed. That makes it easier to move from a package summary to specific source details.
Page selection
Each run records the candidates it considered and the pages it inspected.
Page candidates come from public site structure and are ranked for relevance. The selection report records which pages were included and the reason for each decision. This makes the scope of a run easy to review.
One hosted run can analyze up to 10 selected pages in up to 150 seconds. Browser time and screenshot capacity are bounded, so a slow or media-heavy source may return partial results. The report makes those limits visible instead of implying complete coverage.
The analysis uses a single browser session and processes pages sequentially. This keeps the run focused and allows the report to associate each observation and capture with its source page.
After observations return, the browser-side package builder renders the guides and structured records, validates the file set, and creates the downloadable archive.
The pack describes what the analyzer could observe at capture time. It is evidence for a separate rebuild workflow, not an offline copy of the source website.
See the result
Open a real sample and compare the top-level guide, page-specific notes, structured data, theme output, and captured image.